Skip to content
Available for new projects

Alonso Marcos Muñoz

Data Engineer · Pipelines, data modelling & platforms

I build data pipelines, models and platforms with Python and SQL. I bring professional public-metadata experience and applied projects with Databricks, Spark, Airflow, Kafka and AWS.

Python · SQL · PostgreSQL · Databricks · Spark · Airflow · Kafka · AWS

Albacete, Spain
Alonso Marcos Muñoz

About

I am a Data Engineer at Tragsatec, working on the ImpulsaDATA project for the Spanish Data Directorate. I build and run Python and SQL ETL pipelines that integrate, validate and publish the data catalogue information of 22 Spanish ministries and public bodies.

I cover the full cycle: modelling and transforming data in PostgreSQL and Oracle, automating quality checks and deploying to development, test and production. Within the AgoraData project, I lead the development of the web interface that serves as the front end for all of ImpulsaDATA's backend and Python processes, using Java, Spring Boot, Vaadin and PostgreSQL.

My MSc in Big Data and Cloud Computing gave me hands-on practice with Databricks, Spark, Kafka, Airflow and AWS, and the CAPM certification a structured method to plan scope, risks and deliveries. Day to day I use agentic AI workflows to speed up development, testing and code review while keeping the work traceable.

Professional experience

Tragsatec

TragsatecPresent

Oct 2025 – Present

Data Engineer · ImpulsaDATA

Albacete, Spain

datos.gob.es

I work on the ImpulsaDATA project (public data demand management) for the Spanish Data Directorate. My work focuses on integrating, transforming, validating and publishing the data catalogue information of 22 Spanish ministries and public bodies.

  • Develop and maintain Python and SQL ETL pipelines that automatically collect, clean, validate and publish the data catalogue information of 22 Spanish ministries and public bodies.
  • Design PostgreSQL and Oracle transformations, aggregations and views so that data arrives structured, consistent and ready to be queried and published.
  • Automate quality checks that confirm every dataset meets the European open data standard before publication, so that errors do not reach official catalogues.
  • Adapt and extend CKAN, the project's open data platform, with a shared DCAT-AP-ES profile for every public body, automated catalogue harvesting and geospatial data support.
  • Administer OpenMetadata, the data catalogue and governance platform, in the test environment, use it in production and connect it through its API to the project's metadata conversion tool.
  • Set up and run development, test, pre-production and production environments with Docker, Podman, Git and SSH, keeping deployments documented, repeatable and easy for the team to review.
  • Within the AgoraData project, lead the development of the web interface that serves as the front end for all of ImpulsaDATA's backend and Python processes, using Java, Spring Boot, Vaadin and PostgreSQL. Coordinate and delegate security, testing, accessibility and CI/CD.
  • Contribute to CKAN security hardening (upgrades, TLS encryption, headers and cookies) and verify every fix with tests before closing it.
  • Mentor interns and junior colleagues, document technical decisions and turn team knowledge into reusable guides.
  • Use agentic AI workflows (Claude, Codex and Copilot) for development, end-to-end testing and code review, with rules and context that keep the work traceable.
Tragsatec

Tragsatec

Jun 2025 – Sep 2025

Data Engineer (Internship) · ImpulsaDATA

Albacete, Spain

datos.gob.es

First stage at ImpulsaDATA, focused on designing and building the first version of the project's metadata conversion tool.

  • Designed and built the first version of the project's metadata conversion tool, a Python ETL process that maps source information to the European open data standard and publishes it in CKAN.
  • Added external configuration, execution logs and documentation so the team could run, review and maintain the tool easily.
La Fábrica del Tiempo

La Fábrica del Tiempo

Feb 2024 – Aug 2024

Data & Automation Engineer (Internship)

Albacete, Spain

Data integration and process automation with Power Platform and Microsoft 365 at a consulting and productivity company.

  • Built an internal Power Apps application that brings the company's process management and information together in one place.
  • Automated lead management, notifications and approvals with Power Automate, connecting SharePoint, the CRM and Microsoft 365, improving the efficiency of the targeted processes by more than 25%.
  • Trained the team on the new tools and prepared technical content to support their day-to-day adoption.
Ayuntamiento de Alcázar de San Juan

Ayuntamiento de Alcázar de San Juan

Mar 2019 – Jun 2019

IT Technician (Internship)

Alcázar de San Juan, Spain

Technical support and IT maintenance in a public administration setting.

  • Provided technical support to municipal staff and resolved hardware, software and network incidents in a public administration setting.
  • Maintained equipment and basic infrastructure, supported systems administration and documented incidents to speed up their follow-up.
Soporte ITSistemasRedes

Applied Big Data and cloud

Applied academic projects with architecture, execution evidence and limitations

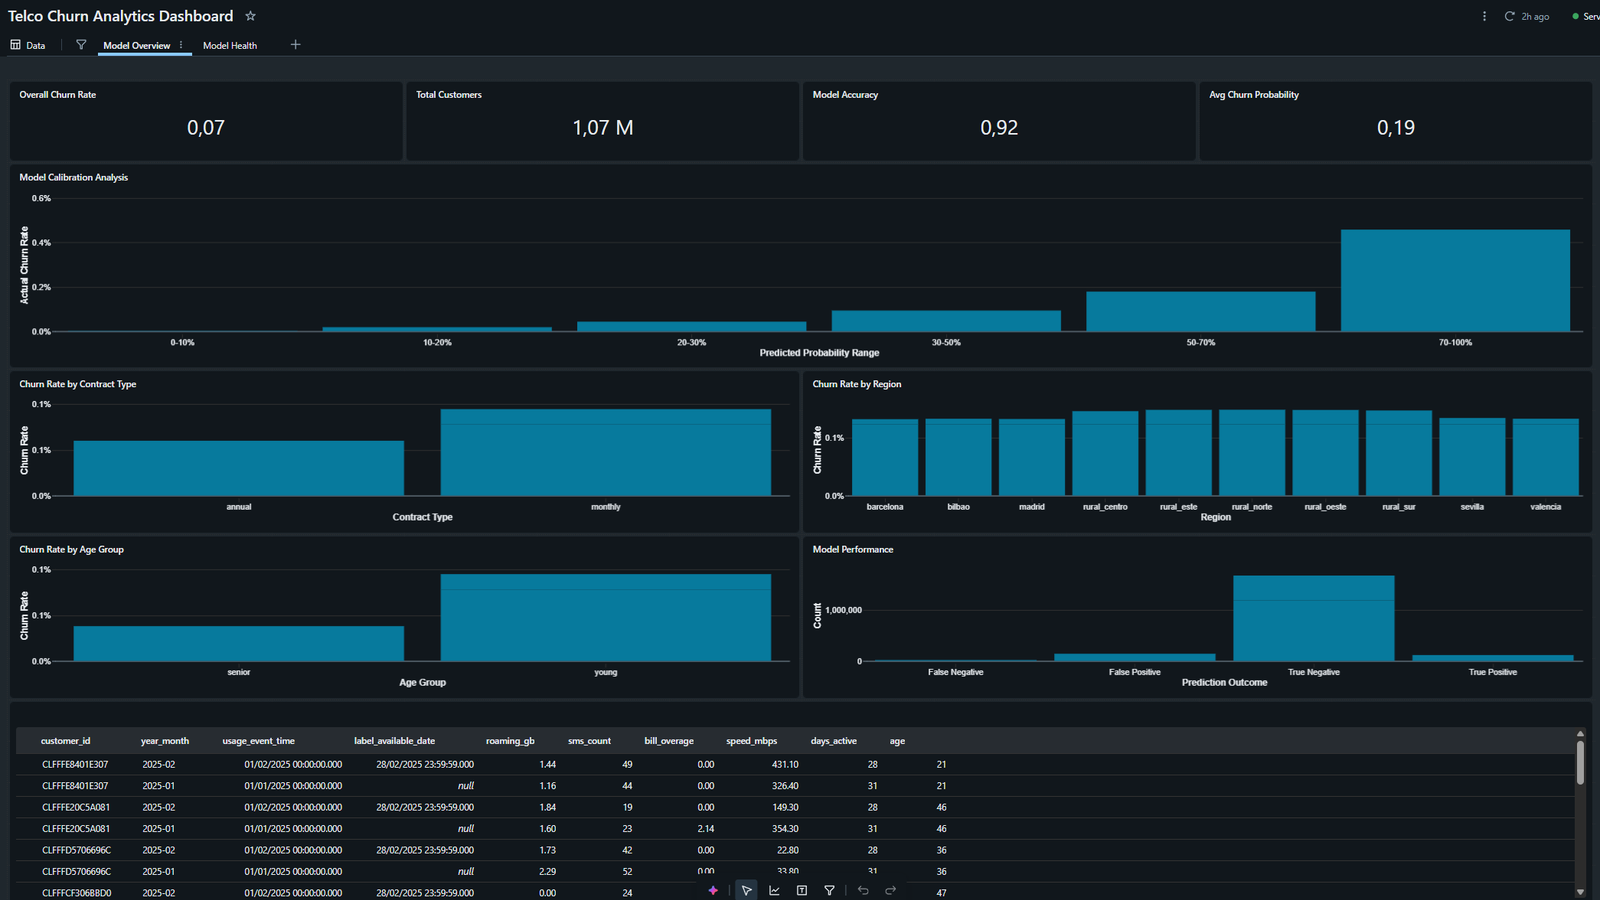
Databricks dashboard showing churn rate, model accuracy, calibration and performance by segment
Big Data · MLOps2026
Applied academic project

Telco churn Lakehouse and MLOps

Co-developed end-to-end data platform that predicts customer churn for a telecom operator on synthetic data using PySpark, Delta Lake, Unity Catalog and MLflow.

DatabricksDelta LakeMLflowUnity Catalog
View case study
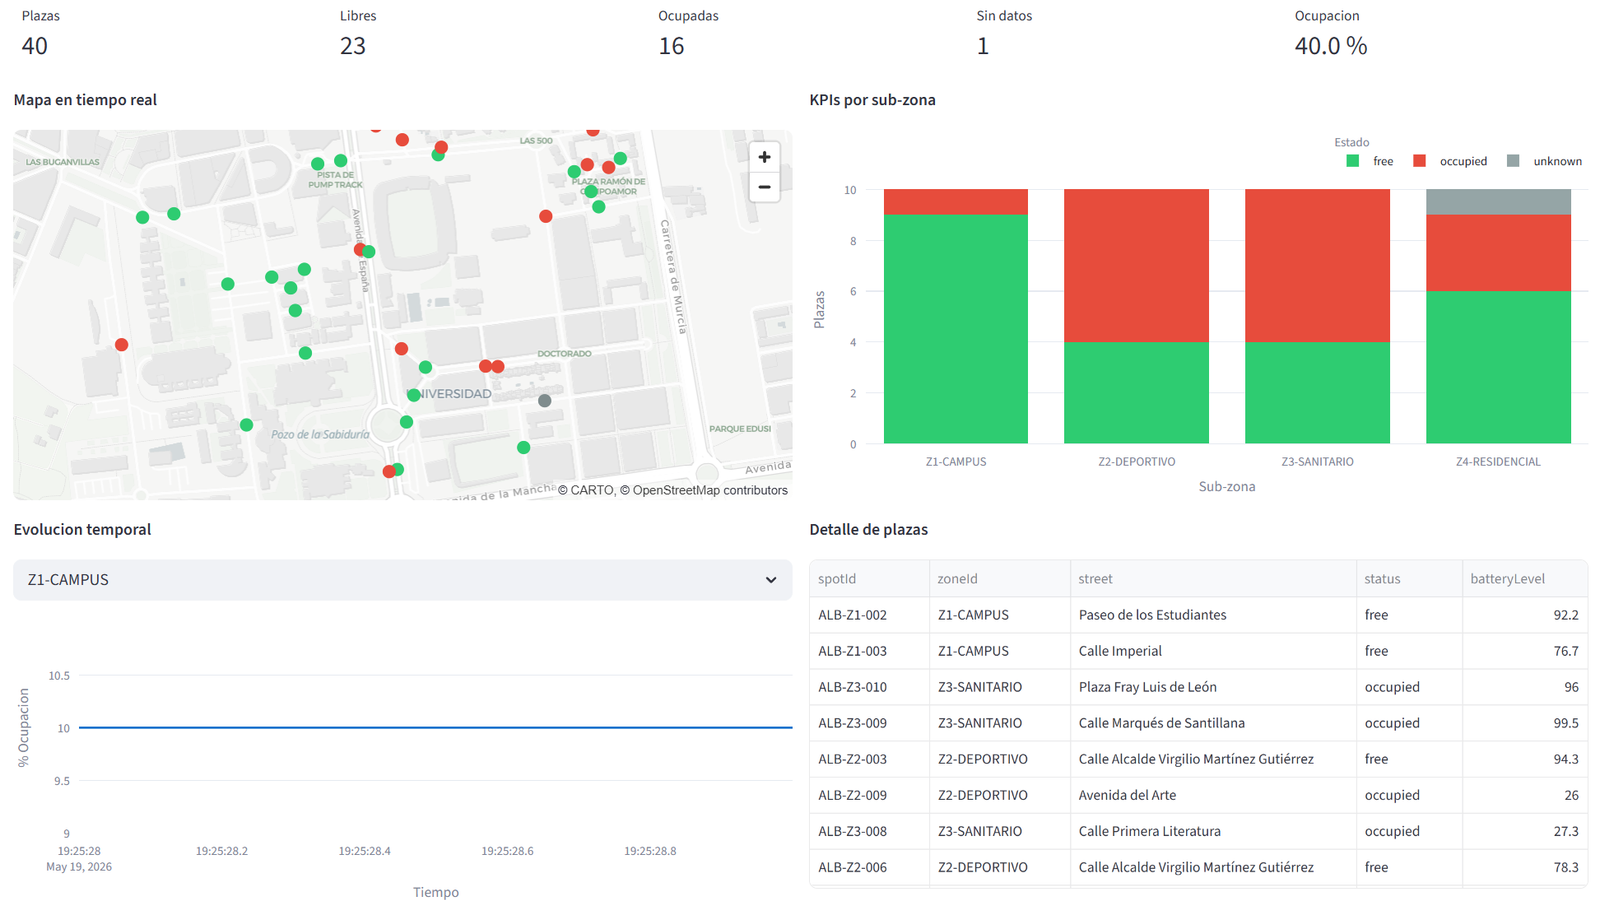
Streamlit dashboard with occupancy KPIs, a real-time parking map and status by sub-zone
Cloud · IoT2026
Applied academic project

Smart Parking Albacete

Cloud IoT platform that collects real-time data from 40 simulated parking sensors and serves it in a web dashboard, using AWS Lambda, DynamoDB and MQTT.

AWS IoTLambdaDynamoDBStreamlit
View case study
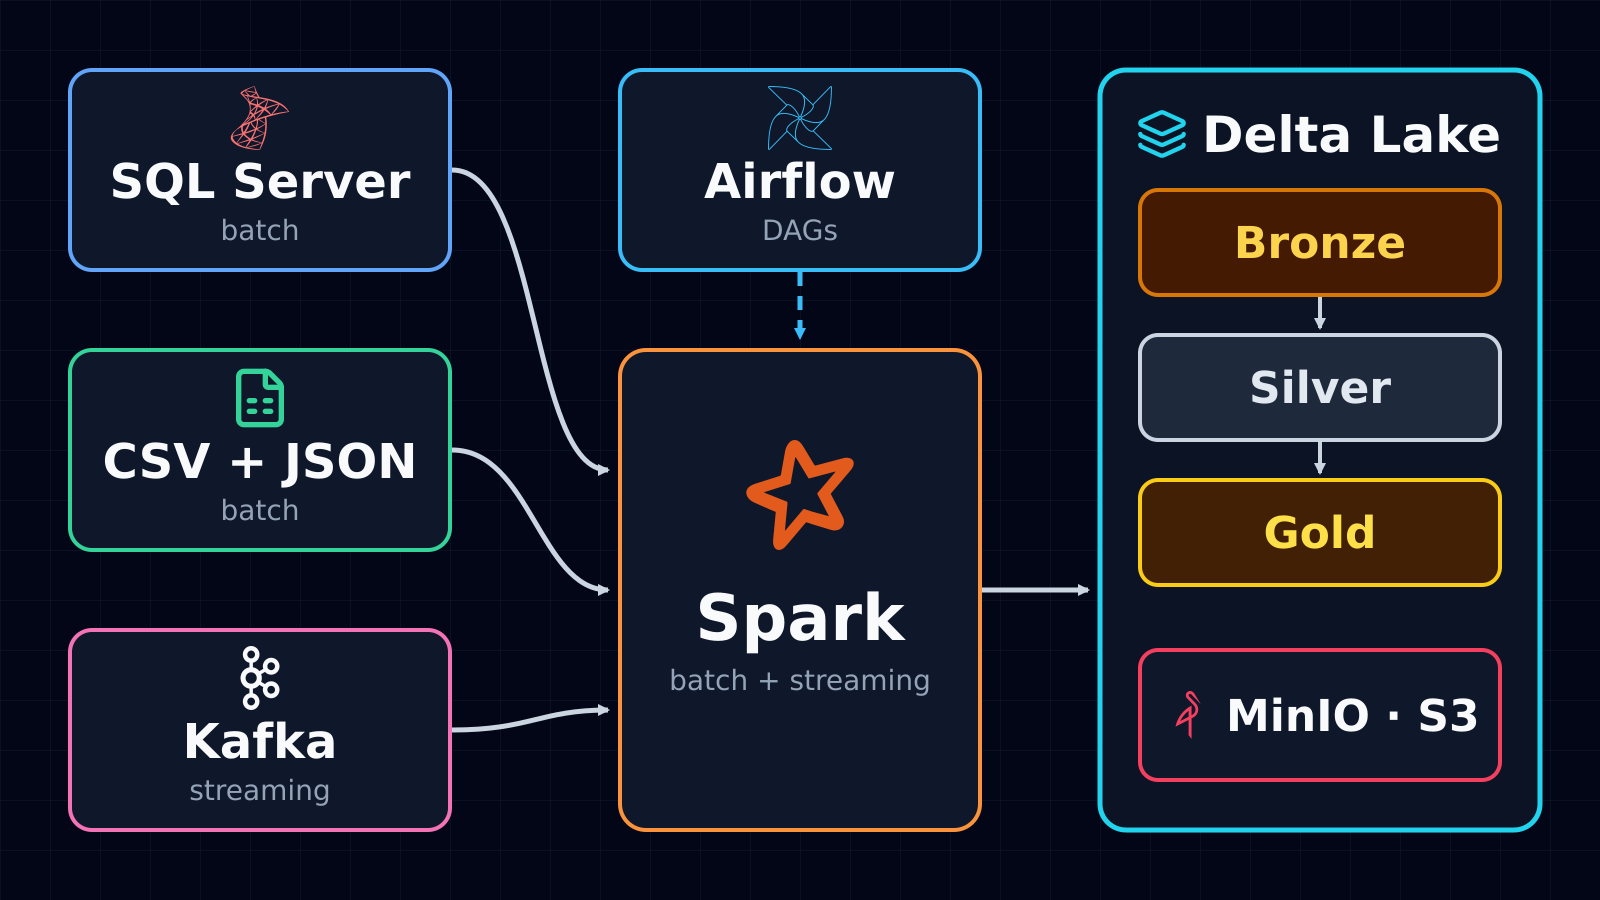
Diagram: SQL Server, CSV and Kafka feed Spark, orchestrated by Airflow, which writes Bronze, Silver and Gold Delta Lake layers on MinIO
Data Engineering2026
Applied academic project

Spark, Kafka and Airflow data platform

Processes batch and real-time data with Spark, Kafka and Airflow and organises it into layers of increasing quality (Medallion architecture) on Delta Lake.

SparkAirflowKafkaDelta Lake
View case study

Tech stack

Data governance & quality

Applied AI & quality

AI harness engineeringContext engineeringAutomatización de flujos técnicosPruebas end-to-end asistidasRevisión técnica de códigoDocumentación reproducible

Management & languages

PMI / CAPMKanbanADOCCEspañol (nativo)Inglés B2

Education & certifications

Project Management Institute
Certification

CAPM

Project Management Institute

Certified foundations of PMI project management.

Let's talk

Open to opportunities in data engineering, data governance and data platforms.

Live GitHub signal

Coding stats

Public activity refreshed from GitHub on every deployment.

Open GitHub profile

Alonso Marcos Muñoz's GitHub

Total commits (2026)
208
Total PRs
21
Merged PRs
95.2%
Total issues
59
Contributions (last 12 months)
313
95%merged

Most used languages

Share of code bytes across owned public repositories.

  • Jupyter Notebook26.8%
  • Python24.8%
  • TeX19.6%
  • TypeScript10.8%
  • HTML7.7%
  • Astro3.9%

Public activity onlyIncludes activity from my previous account @AlonsoMarcosMUpdated 30 Sept 2026GitHub API